Localization quality cannot be judged by counting errors alone. Ten punctuation issues and one mistranslated safety instruction may create radically different consequences. A defensible quality framework measures linguistic accuracy, functional usability, process performance, and signals from users and the business. It also considers how evidence is collected: error severity, sampling coverage, evaluator reliability, and scoring rules all influence what a quality score means. Organizations should define content-specific requirements and acceptable risks before evaluation, establish clear escalation rules for consequential defects, and use the results to guide decisions and continuous improvement rather than simply ranking translation providers.
Five Key Takeaways
- Error counts do not tell the whole story. Severity, context, and potential consequences determine whether a translation defect is acceptable, requires correction, or creates significant risk.
- Quality must be defined by purpose. Product interfaces, marketing campaigns, technical documentation, and safety instructions require different evaluation priorities and review coverage.
- A score is only as reliable as its evidence. Sampling methods, evaluator consistency, scoring configurations, and normalization determine whether conclusions are defensible.
- Automatic metrics support—but do not replace—qualified evaluation. Human review, automated QA, quality estimation, and AI-based assessment have different strengths and limitations.
- Quality measurement should drive improvement. The most useful metrics connect defects to their causes, corrective actions, operational decisions, and user impact.
Why Error Counts Are Necessary—but Insufficient
Translation error counts are useful because they reveal recurring problems, support comparisons under controlled conditions, and help teams identify where corrective work may be needed.
However, the number of errors identified does not necessarily indicate how damaging those errors are.
Consider two illustrative translation projects.
Project A contains ten minor punctuation inconsistencies in an internal information document. The text remains understandable, and users can complete their intended tasks.
Project B contains one missing negation in a safety warning, changing an instruction from “Do not operate” to “Operate.”
Although Project B has fewer errors, its potential consequences are substantially more serious.
The same distinction applies to five awkward stylistic choices in a marketing draft compared with one mistranslated contractual obligation. Both involve quality defects, but their consequences demand different responses.
Content context also matters. An ambiguous instruction in an internal draft may be clarified before use. The same ambiguity on a public product page could mislead customers across multiple markets.
These examples are illustrative, not actual project findings.
Error frequency describes how often problems are observed. Error severity describes how much those problems matter.
A meaningful localization quality measurement system needs both, alongside evidence of how content will be used.
Define Quality Before Measuring It
Before selecting translation quality metrics, organizations must establish what successful localization means for the content being evaluated.
A useful quality specification should identify the intended audience, intended use, publication channel, linguistic and functional requirements, acceptable risk, review depth, consequences of error, and evidence required for approval.
For example, internal training material may prioritize accurate meaning, consistency, and clarity. Consumer marketing content additionally requires brand voice, cultural appropriateness, and persuasive communication. Technical documentation may demand specialist terminology, precise specifications, and complete procedural instructions.
These differences illustrate fit-for-purpose translation quality: content must meet the requirements of its intended application.
Fit for purpose does not mean accepting avoidable inaccuracies or lowering essential quality standards to reduce costs. It means applying appropriate controls to different risks while preserving fundamental requirements for accurate and usable communication.
ISO 11669:2024 provides guidance on translation project specifications, needs analysis, risk assessment, and workflow planning. Its approach reinforces the importance of defining requirements before evaluating results.
Quality requirements should also specify who can approve content, which defects require escalation, and what evidence supports a release decision.
Without these agreements, a passing score may reflect an evaluator’s assumptions rather than the organization’s actual requirements.
Four Layers of Localization Quality
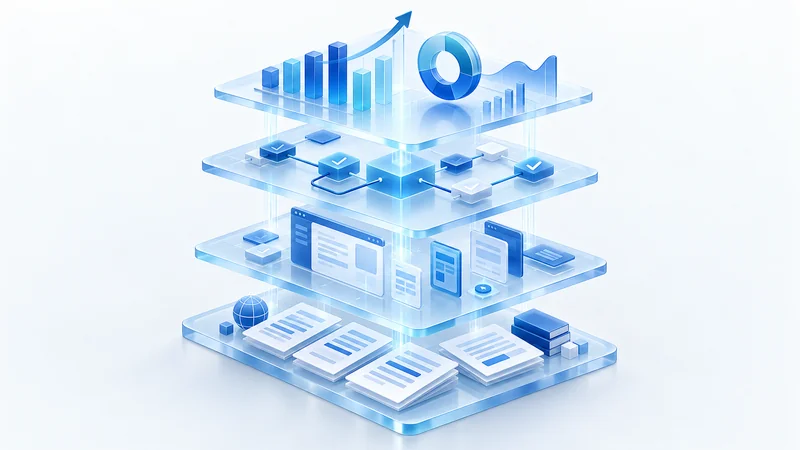
Linguistic evaluation is essential, but enterprise localization quality extends beyond translated words. A practical framework organizes localization quality metrics into four complementary layers.
Layer 1 — Linguistic Output Quality
This layer evaluates the translation itself.
Core dimensions include accuracy, completeness, terminology, fluency, style, and locale conventions.
Linguistic Quality Assurance (LQA) can identify omissions, mistranslations, inconsistent terminology, inappropriate register, and other defects against defined requirements.
Layer 2 — Functional and Experience Quality
A linguistically accurate translation may still fail when integrated into a website, software application, or multimedia product.
Functional evaluation examines layout, interface behavior, text truncation, links, forms, placeholders, search and navigation, subtitle synchronization, and accessibility.
For example, a correctly translated checkout button provides little value if its localized text breaks the interface or prevents users from completing a purchase.
Layer 3 — Process Quality
This layer measures the reliability of localization operations.
Relevant indicators include on-time delivery, rework, review cycles, query resolution, version control, approved language-asset reuse, and escaped defects—problems discovered after the intended quality controls have been completed.
Consistently high rework may indicate inadequate source preparation, missing context, unclear terminology, or ineffective workflow routing.
Layer 4 — User and Business Outcomes
The final layer considers whether localized content supports intended user and organizational outcomes.
Potential indicators include task completion, customer comprehension, support volume, engagement, conversion, product adoption, and operational or regulatory incidents.
These indicators require careful interpretation. A lower conversion rate does not automatically establish that translation quality caused the decline. Pricing, product availability, market conditions, and interface design may also influence performance.
The four layers therefore provide different kinds of evidence:
Linguistic correctness, functional usability, operational reliability, and business outcomes should be evaluated together without assuming they are interchangeable.
This is an enterprise management framework, not a four-layer structure prescribed by ISO 5060. For related service-level governance considerations, see Quality Management.
Error Typology, Severity, and Quality Thresholds
Structured translation quality evaluation requires a consistent method for describing errors and assigning significance.
Three related concepts are useful to distinguish.
LQA refers to operational activities used to assess and improve the linguistic quality of localized content.
Translation Quality Evaluation (TQE) is a structured assessment of translation output against defined criteria.
Multidimensional Quality Metrics (MQM) is an analytic evaluation framework that provides an error typology and configurable scoring models.
The MQM Council describes how error categories, subtypes, severity levels, and penalty weights can produce numerical quality scores.
An evaluation record should distinguish the error category, specific error type, severity, applicable penalty, evaluation volume, and acceptance criteria.
A practical severity model may distinguish:
Minor: A defect with limited impact on meaning, usability, or the intended experience.
Major: A defect that substantially affects meaning, reliability, usability, or important content requirements.
Critical: A defect that renders content unfit for purpose or presents a risk of serious harm.
Some configurations also include a neutral classification for acceptable alternatives or non-penalized observations.
Severity determines the significance of a particular instance; category identifies the nature of the problem. Depending on the approved scoring configuration, penalties may reflect severity, error type, or both.
Normalization then relates penalty totals to a defined evaluation volume.
A quality threshold represents an agreed acceptance criterion—not an industry-wide guarantee.
ISO 5060:2024 provides guidance for human analytic evaluation of human translation, post-edited machine translation, and unedited machine translation. It addresses error-based assessment, evaluator competence, and sampling.
Neither ISO 5060 nor MQM should be presented as establishing one universal passing score for every organization, language, or content type.
Why Severity Matters More Than Raw Count
Severity connects translation defects to their potential consequences.
The following scenarios illustrate why identical error counts can require very different decisions.
All examples and severity classifications are illustrative. Actual assignments depend on content requirements and risk assessment.
| Error | Content context | Illustrative severity | Potential consequence | Required action |
|---|---|---|---|---|
| Missing negation | Medical safety instruction | Critical | Reversed safety meaning | Block release and obtain specialist verification |
| Incorrect specification | Industrial equipment documentation | Major or Critical | Incorrect product selection or unsafe operation | Verify technical data and correct affected content |
| Inconsistent approved term | Software help center | Minor or Major | User confusion | Correct terminology and update language assets |
| Awkward style | Internal information document | Minor | Reduced readability | Resolve during normal review |
| Broken placeholder | E-commerce checkout | Major | Incorrect information or disrupted transaction | Correct the resource and retest functionality |
| Incorrect legal entity name | Commercial contract | Critical | Misidentification of a contracting party | Hold publication and obtain legal-linguistic review |
| Subtitle timing issue | Safety training video | Major or Critical | Misunderstood safety instructions | Correct synchronization and verify playback |
A severity-weighted translation quality score helps distinguish low-impact defects from consequential ones.
However, aggregation introduces another problem: a favorable average may conceal a critical issue.
An organization should therefore consider explicit release-blocking or escalation conditions for specified critical defects, independent of its aggregate quality score.
A good average cannot compensate for an unresolved defect that makes the content unsafe or materially misleading.
Different Content Needs Different Quality Models
Different content categories require different evaluation priorities because users rely on them in different ways.
A single organization-wide quality threshold can obscure these differences.
| Content type | Primary quality priorities | Appropriate review emphasis | Business or user indicator |
|---|---|---|---|
| Internal content | Meaning, completeness, clarity | Representative sampling with targeted checks | Internal task accuracy |
| Customer support | Accuracy, understandable instructions | Issue-based review and coverage of consequential guidance | Resolution and repeat contacts |
| Product UI | Meaning, terminology, usability | In-context testing and critical-flow coverage | Task completion |
| Marketing | Message, tone, brand consistency | Market-oriented editorial review | Engagement and conversion |
| Technical documentation | Precision, terminology, specifications | Specialist review and risk-based coverage | Product support incidents |
| Legal content | Obligations, entities, precise meaning | Qualified legal-linguistic review of material provisions | Corrections and legal escalations |
| Medical and safety content | Safety meaning, completeness, terminology | Specialist verification and full coverage of critical statements | Safety-related incidents |
| Multimedia | Meaning, synchronization, readability | Linguistic and playback review | Comprehension and accessibility feedback |
These are proposed evaluation approaches, not universal compliance rules.
Sampling may be appropriate for routine content and for measuring broader production performance. Yet critical instructions, contractual provisions, or safety-related information may require complete review of the consequential elements.
The objective is not to establish separate arbitrary scores for every department. It is to apply a coherent measurement methodology while adjusting dimensions, coverage, and acceptance rules to content risk.
This principle is particularly important when selecting workflows within broader Language Translation Solutions.
Evaluating Human, Machine, and AI Translation with Consistent Criteria
Localization teams increasingly work with human translation, post-edited machine translation, unedited machine translation, LLM-generated translation, and AI-assisted human translation.
The production method is relevant to workflow design, but it should not automatically determine the quality conclusion.
A human translation can contain serious omissions. Machine translation may deliver acceptable output for a defined lower-risk task. An AI-generated translation may read fluently while introducing unsupported information.
All outputs should therefore be evaluated against applicable requirements for meaning, completeness, terminology, usability, and risk.
AI-generated translations deserve particular attention to unsupported additions, omitted qualifications, inconsistent terminology, and errors concealed by fluent wording.
Post-edited machine translation should be evaluated as the final delivered output, while the efficiency and effectiveness of post-editing are measured separately.
Organizations should also distinguish output quality from workflow performance. A lower-cost or faster translation method does not establish that its output meets the required standard.
ISO 18587:2017 addresses full human post-editing of machine translation output, while ISO 17100:2015 addresses translation service processes and resources. These standards concern different aspects of translation delivery and should not be treated as interchangeable quality scores.
The central principle is straightforward: use common evaluation dimensions where applicable, then add controls appropriate to the production method and content risk.
For a related discussion of how work should be allocated between AI and human specialists, see AI Localization Strategy.
Human Evaluation vs. Automatic Translation Quality Metrics
Human assessment and automatic metrics answer different evaluation questions.
No single method provides comprehensive evidence for every translation, language, or use case.
| Evaluation method | Main strengths | Key limitations | Appropriate application |
|---|---|---|---|
| Human analytic evaluation | Identifies specific defects and severity | Requires trained evaluators; subject to disagreement | Acceptance decisions, root-cause analysis |
| Holistic human review | Captures overall readability and suitability | Less diagnostic and potentially subjective | Editorial and audience-focused assessment |
| Reference-based metrics | Fast, repeatable comparison against reference translations | Sensitive to references, datasets, and metric design | Benchmarking and controlled experiments |
| Reference-free quality estimation | Supports evaluation without human reference translations | Predictions require validation and calibration | Review prioritization and large-scale screening |
| Automated QA checks | Efficiently detects numbers, tags, placeholders, and defined terminology problems | Limited understanding of meaning | Structural and technical validation |
| AI-based evaluation | Can flag potential semantic or contextual problems at scale | May produce inconsistent or incorrect judgments | Assisted review and issue discovery |
BLEU, COMET, and Quality Estimation
BLEU measures aspects of correspondence between machine-generated translations and reference translations. It can be useful in controlled comparisons, but lexical overlap does not fully represent semantic accuracy or fitness for purpose.
COMET introduced a neural framework for machine translation evaluation using learned relationships with human quality judgments. Different COMET models and configurations have different requirements and limitations.
Reference-free quality estimation predicts translation quality without requiring a human reference translation. It is useful for prioritizing review, but a prediction should not be confused with a verified assessment.
The WMT 2025 automated evaluation study reported differences between system-level and segment-level metric performance, as well as persistent challenges in detecting errors accurately across diverse languages.
These findings reinforce an important operational distinction.
An automatic metric can help identify likely quality differences. It cannot, by itself, certify that specific content is ready for publication.
For consequential content, organizations should combine automated assessment with appropriately qualified, independently validated human review.
Sampling and Coverage: Know What the Evidence Represents
Large localization programs cannot always evaluate every translated segment manually. Sampling makes structured evaluation more practical, but introduces uncertainty.
The first step is defining the population being evaluated: which projects, releases, language pairs, content categories, and production workflows are included.
The selected sampling method should match the decision the organization needs to make.
Random sampling can support population-level estimates when a properly defined sampling frame and appropriate statistical methods are used.
Stratified sampling divides content into relevant groups, such as language, content type, or risk level, to ensure intentional coverage. Disproportionate sampling may require weighting before calculating a population-wide estimate.
Risk-based sampling prioritizes content with greater potential consequences, such as safety information or critical user journeys.
Triggered review responds to complaints, recurring defects, system changes, or other warning signals.
New languages, new suppliers, and newly introduced AI workflows may also warrant increased evaluation coverage until sufficient performance evidence has been collected.
The MQM Council’s sampling guidance discusses different approaches and the challenges created by nonuniform content.
Sampling results must be interpreted within their limits.
A small sample containing no critical errors does not prove that none exist elsewhere. Conversely, a sample deliberately concentrated on high-risk content should not automatically be interpreted as representative of all production output.
There is no defensible universal sample percentage for every localization program.
Sampling decisions should reflect risk, content variability, operational stability, and the strength of the conclusions the organization intends to draw.
Evaluator Reliability: Can Different Reviewers Reach Comparable Conclusions?
Even carefully designed scoring systems can produce unreliable results if evaluators interpret the rules differently.
One reviewer may classify a terminology issue as minor, while another considers the same issue major. Evaluators may also disagree over whether a phrase represents an actual error or an acceptable linguistic alternative.
When disagreements are frequent, quality comparisons become less credible.
Reliable evaluation requires clear annotation guidelines, representative examples, appropriate language competence, subject-matter expertise, and structured evaluator training.
Calibration exercises help reviewers apply the same definitions. Double annotation allows organizations to compare independent judgments, while disagreement review identifies ambiguities in the guidelines.
Blind evaluation can also reduce bias where reviewers would otherwise know the supplier, translation technology, or previous quality score.
Inter-rater reliability measures the consistency of judgments between evaluators. Organizations can track agreement on error identification, categories, and severity, paying particular attention to disagreements involving major or critical defects.
The MQM Council’s reliability guidance emphasizes that measurement must be both consistent and valid.
An evaluator’s score should not be treated as objective merely because it is expressed numerically.
Normalize Before Comparing Quality Scores
A translation quality score becomes misleading when organizations compare results produced under substantially different conditions.
Consider a short marketing campaign evaluated in full and a large technical documentation project assessed through a limited sample.
Even if both receive the same score, their evidence coverage, content complexity, and risk exposure may be different.
Normalization can account for evaluation volume by expressing weighted penalties relative to a defined denominator, such as reviewed source words.
However, the denominator and calculation rules must remain consistent. Word-based measures may also require adaptation or careful interpretation across languages with different segmentation characteristics.
Organizations should additionally control for content type, language pair, risk classification, workflow, reviewer calibration, sample design, and scoring configuration.
Comparisons should preferably use comparable content groups and consistent evaluation rules.
Calibrated scores can make thresholds easier to interpret, but separately calibrated systems are not necessarily directly comparable.
The dashboard should therefore show both the reported score and its measurement context.
Normalization improves comparability; it does not eliminate differences in what was measured or how it was evaluated.
A Localization Quality Dashboard That Supports Decisions
An effective translation quality dashboard should help managers identify risk, investigate performance, and assign action—not simply display an attractive overall percentage.
Four reporting areas provide a useful structure.
| Dashboard area | Recommended indicators | Main decision |
|---|---|---|
| Output Quality | Weighted error score, critical defects, terminology issues, evaluation coverage | Is the delivered content acceptable? |
| Process Quality | Rework, approval cycles, review effort, turnaround stability | Where is the workflow underperforming? |
| Operational Risk | Escaped defects, repeated errors, high-risk incidents, unresolved exceptions | What requires escalation or stronger controls? |
| Business Signals | User feedback, support issues, task success, market performance | Which outcomes warrant further investigation? |
The dashboard should display relevant filters and supporting metadata, including language, content type, project, reporting period, evaluated volume, sampling method, and scoring version.
Critical defects should remain visible separately from aggregate averages.
For example, a program may show improving weighted quality scores while experiencing recurring errors in product specifications. The overall trend is useful, but the recurring problem deserves investigation regardless of the average.
Business metrics also need context. A rise in support requests after a localized product release may indicate a content problem, but product changes, demand patterns, or operational issues could also explain the increase.
A decision-oriented dashboard should therefore combine performance trends, critical exceptions, evidence coverage, and accountable next actions.
The purpose is to support operational judgment, not to replace it with a single composite index.
From Quality Scores to Root-Cause Improvement
Translation quality evaluation becomes most valuable when organizations use the findings to prevent repeated problems.
Consider a recurring terminology inconsistency across several product releases.
Correcting each occurrence may resolve the immediate defects, but it does not explain why they continue to appear.
Investigation may reveal an outdated glossary, inconsistent translation memory, missing source context, or conflicting reviewer instructions.
Other recurring defects may originate from poor source-content quality, incorrect workflow routing, insufficient specialist expertise, tool configuration, unrealistic delivery schedules, or limitations in the translation engine or AI model.
These are operational causes, not simply individual translator failures.
A structured improvement cycle connects the finding to corrective action:
Observed defect → Root-cause investigation → Corrective action → Assigned owner → Re-evaluation → Recurrence monitoring
For example, a missing placeholder may require changes to string-handling rules and automated validation. Repeated omissions may require improved source preparation, context availability, or evaluation of the translation workflow.
The MQM Council’s root-cause guidance provides additional categories for investigating issues across source content, language assets, internationalization, and production.
Quality data should also inform supplier discussions, but accountability must follow verified evidence.
The objective is to reduce the conditions that produce defects—not merely to count and penalize the defects after they occur.
Common Localization Quality Measurement Mistakes
Several measurement practices can create misleading conclusions, even when organizations invest heavily in evaluation tools.
Treating every error equally. Raw counts obscure differences between cosmetic issues and consequential mistranslations.
Using one threshold for every content type. A uniform score may disregard material differences in content purpose and risk.
Comparing unnormalized scores. Different evaluation volumes, sampling strategies, or scoring rules can distort comparisons.
Measuring only supplier output. Localization problems may originate in source content, terminology resources, integration, or internal review.
Using small samples to support broad claims. Limited evidence cannot establish reliable population-wide quality without appropriate sampling and statistical justification.
Changing scoring rules without documentation. Unrecorded changes can create apparent performance improvements that reflect measurement changes rather than actual quality.
Allowing AI to evaluate its own output without independent controls. Shared model biases or evaluation weaknesses may lead to missed defects.
Focusing on averages while hiding critical errors. Strong aggregate results should not override documented serious risks.
Using quality data only to penalize vendors. Punitive measurement can discourage transparent reporting and distract from systemic improvement.
A credible program must evaluate the reliability of its measurements as carefully as the quality of the content being measured.
Implementing a Defensible Localization Quality Measurement System
Organizations do not need to build an excessively complicated scorecard before measuring quality. They need a controlled framework that can be tested, explained, and improved.
A practical implementation follows four stages.
Stage 1 — Define the Framework
Begin by classifying content according to intended use and risk.
Select the quality dimensions that matter for each content category. Establish error types, severity definitions, acceptance rules, and escalation conditions.
Document the guidelines before formal evaluation begins.
Stage 2 — Build Reliable Evidence
Train evaluators using representative content and clear annotation examples.
Choose sampling methods appropriate to the population, content risk, and evaluation objective.
Establish a baseline that records not only scores but also sample coverage, denominators, reviewer conditions, and scoring rules.
Stage 3 — Pilot and Calibrate
Pilot the scorecard across selected languages, content types, and workflows.
Review disagreement between evaluators, examine false positives and missed defects, and test how the scoring system responds to consequential errors.
Revise ambiguous guidelines and scoring configurations where the evidence justifies changes.
Stage 4 — Improve and Govern
Connect recurring findings to root-cause investigations and corrective actions.
Assign ownership for release decisions, evaluation guidelines, calibration, dashboard reporting, and periodic review.
Update acceptance thresholds using documented operational evidence, content requirements, and changes in risk.
For AI-supported workflows, the NIST AI Risk Management Framework provides broader guidance on measurement validity, uncertainty, monitoring, and governance.
A successful implementation is not defined by reaching a predetermined universal score. It is defined by whether the measurement system produces sufficiently reliable evidence for the decisions it is expected to support.
Final Strategic Takeaway: Measure to Decide, Then Improve
Localization quality management should move beyond counting defects or comparing supplier rankings.
Effective programs define what quality means for each use case, identify consequential errors, evaluate the reliability of the evidence, and connect findings to corrective action.
They recognize that language quality, functional performance, process effectiveness, and business outcomes are related but distinct.
The strongest localization quality programs do not ask only, “How many errors were found?”
They ask:
“Which errors mattered, why did they occur, what risk did they create, and what decision should follow?”
That is how localization quality metrics become a foundation for better governance, more reliable operations, and meaningful continuous improvement.
FAQ
How is localization quality measured?
Localization quality is measured through linguistic evaluation, functional testing, process indicators, and user or business signals. A reliable framework considers error categories, severity, sampling coverage, evaluator consistency, and the intended use of the content.
What are the most useful translation quality metrics?
Useful metrics include severity-weighted error scores, critical defect counts, terminology consistency, evaluation coverage, rework, and escaped defects. Their value depends on consistent definitions and appropriate interpretation. No single metric represents every dimension of translation quality.
What is MQM in translation quality?
Multidimensional Quality Metrics (MQM) is a structured framework for analytic translation quality evaluation. It uses defined error types, severity levels, and configurable scoring models to support consistent assessment of translation output.
What is the difference between LQA and translation quality evaluation?
Linguistic Quality Assurance generally refers to operational activities for checking and improving linguistic content. Translation Quality Evaluation is a structured assessment of output against defined criteria. TQE can serve as one component of a broader LQA or quality management program.
Can AI evaluate translation quality?
AI systems can identify potential translation problems, estimate quality, and help prioritize human review. However, model-generated judgments may be inconsistent or incorrect. Important acceptance decisions require appropriate validation, and high-risk content may need independent human or specialist evaluation.
How large should a translation quality sample be?
Sample size depends on the evaluation population, content variability, risk, desired statistical confidence, and purpose of assessment. Random or stratified sampling may support broader estimates, while critical content can require targeted or complete review. There is no universal sample size suitable for every localization project.


